7 Approaches to Reduce Inference Latency in Your LLM Workflows
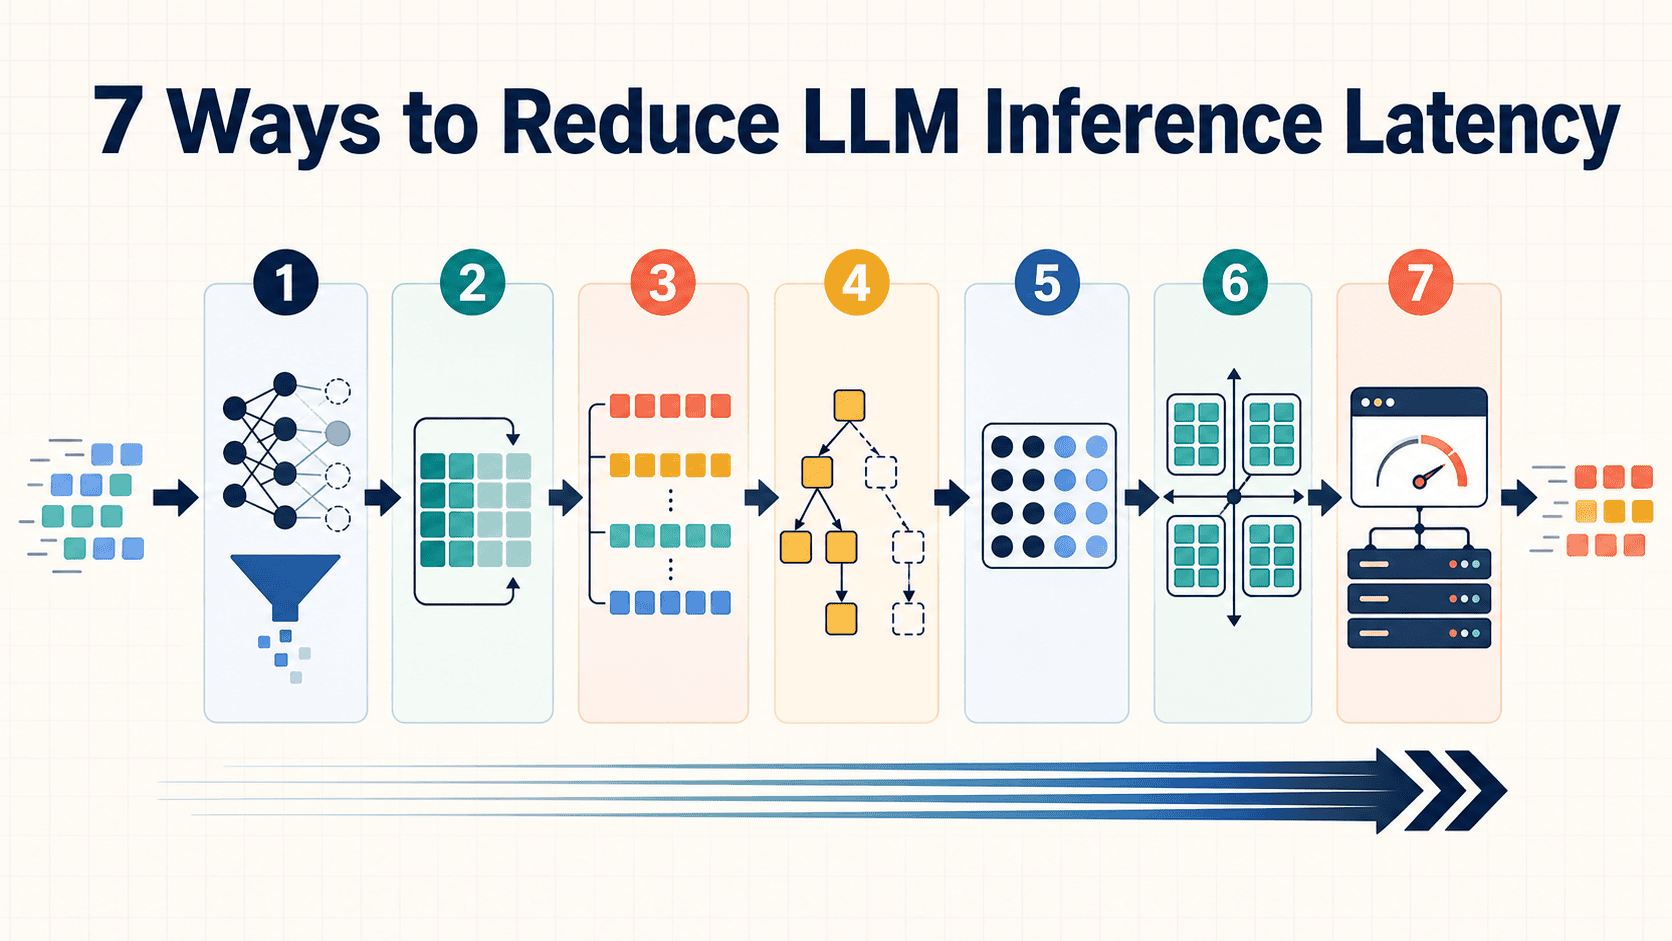
7 Approaches to Reduce Inference Latency in Your LLM Workflows
Annons
Annons
From quantization to speculative decoding, here are seven engineering strategies to ship faster, more responsive generative AI applications in production.

Source: KDnuggets — Published — Category: Open Source

🔗 Read full article on KDnuggets →
⚡ Popular — 67 views
Annons
Annons