[AINews] The Future of Latent Space
It’s been an absolutely MONSTER week already, from new Chinese Open Weight Frontier Lab claiming the throne for the first time, to new SOTA LLM and price cuts from Anthropic and OpenAI, to Meta Connect, to TypeSafe AI’s $10B fundraise after our exclusive podcast this weekend (already one of our top…
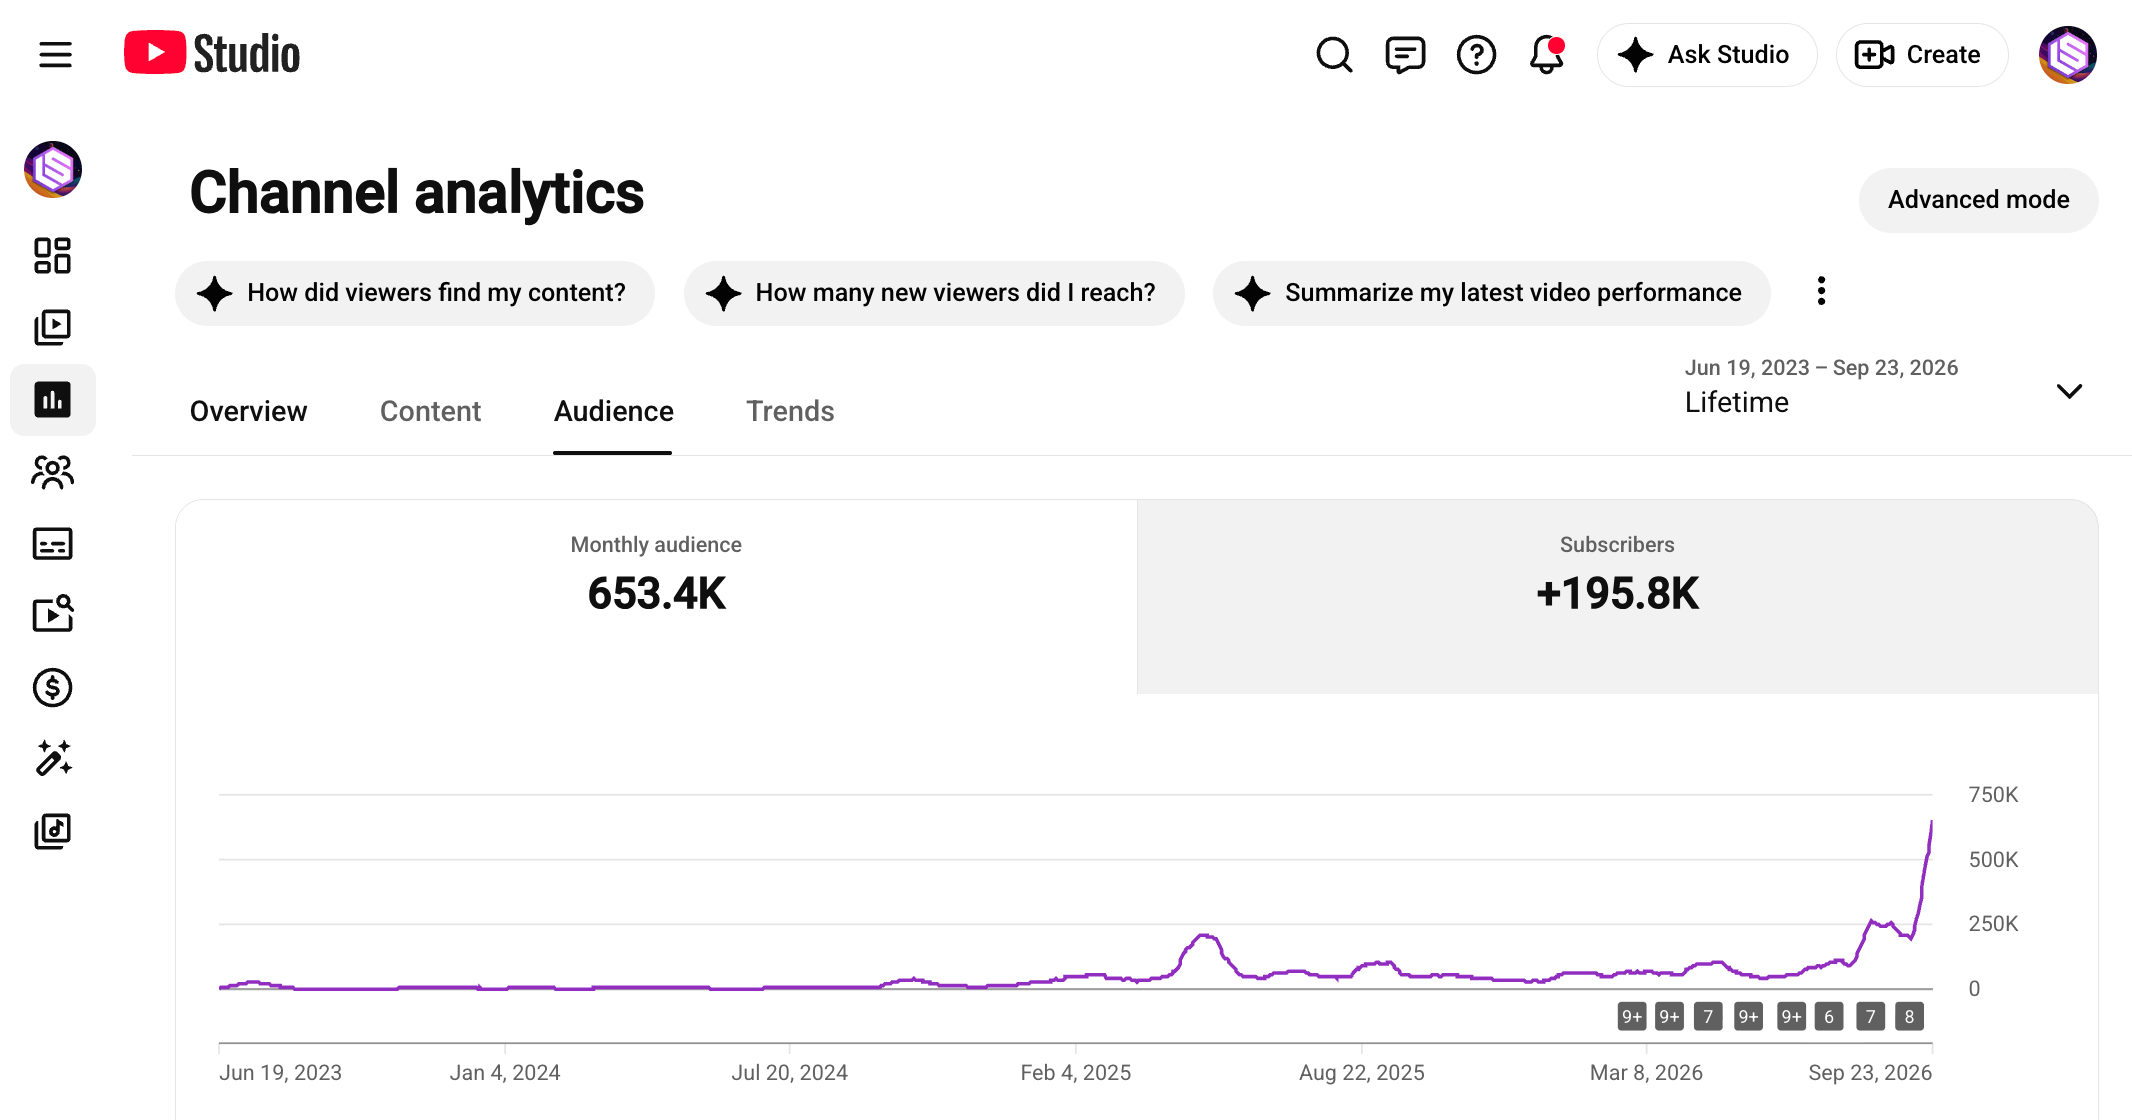
It’s been an absolutely MONSTER week already, from new Chinese Open Weight Frontier Lab claiming the throne for the first time, to new SOTA LLM and price cuts from Anthropic and OpenAI, to Meta Connect, to TypeSafe AI’s $10B fundraise after our exclusive podcast this weekend (already one of our top of all time, with two pods on genomic language models and AI scientists sending us above heavyweights like TBPN and MKBHD in Apple Podcasts, and helping cross 200K on YouTube). Today is the calm before the DevDay storm, so we’re taking some time to share some long overdue changes we are making to Latent Space in the coming week:Plans for AINews v3: This op-ed you are reading has always been human-authored by swyx (hi!!) every weekday for the last 3 years, and what started as a simple way to solve Discord fatigue eventually became LS’s newspaper: an awkward hybrid of Money Stuff mixed with engineer-tuned TechMeme mixed with AI writing evals that somehow grew to over 200k subscribers. Meanwhile, the Latent Space Discord is now tens of thousands of members and yet quieter than ever with increasing amounts of self promotional spammers. The solution is obvious: merge the “job to be done” of the LS Discord and AINews.Plans for a new home: with the success of our AI for Science pod and writing, and new podcasts from food to FDE rising, we’re slowly becoming a multi-show, multi-newsletter network of the best technical news, analysis and edutainment in AI. We’ll be exploring a migration to Beehiiv and a new homepage.Open for business: with a new Business/Ops Manager and Head of Editorial, we are once again reopening for sponsorships (business@latent.space) and PR/tips! That said, join us next week at Supabase Select in SF!!! Supabase is the universally preferred integrated backend by every frontier model and we’re excited to interview their founders on their incredible journey building a fully remote open source database company from 0 to $10B, and see what’s next.Sponsored by SupabaseEverything Supabase has been building will be unveiled on October 2 — live for one day in San Francisco!See what Supabase is launching →AI News for 9/23/2026-9/24/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!AI Twitter RecapFrontier Model Wave: Claude Opus 5.5, GPT-6 Astra/Sol/Luna, Gemini 3.8 Flash, and Xiaomi MiMo-V2.6-ProClaude Opus 5.5: Opus 5.5 now leads SimpleBench at 88.4%. On vision evals, @skalskip92 ranks it Anthropic’s best vision model to date: better than Fable 5 and GPT-6 Sol, worse than GPT-6 Astra, at about 60% lower cost than Fable 5.1.Reasoning effort: On Terminal-Bench-Science, Opus 5.5 climbs from 24% at low effort to 62% at xhigh, then drops to 59% at max. @theo recommends avoiding “max” because it imposes a minimum reasoning budget.Terminal-Bench-Science leaders: GPT-6 Astra and Opus 5.5 lead Fable 5.1 by about 20 points. The best model from outside those two labs is Qwen3.8 Max at 12%.Community sentiment: Many say the $200 Claude Code plan now beats Codex. Astra remains the preferred review/audit model.GPT-6 family:Astra reportedly beat NetHack on its 3rd try.Luna [Max] entered Code Arena WebDev at #24 (1593), +74 over GPT-5.6 Luna, at about $0.40/Mtok blended.DOOM agent matches show Astra at 82.5% win rate, Sol fastest, Luna best wins/$.Gemini 3.8 Flash: Scores 41 on the AA Intelligence Index at 291 tok/s with 1M context, and is free in Cline. On ARC-AGI it posts 89.2% on v2 at $0.40/task and 98.5% on v1. On v3 it scores 10.4% with the standard harness and 35% with the provider harness.Xiaomi MiMo-V2.6-Pro: Released under MIT, it is omni-modal with 1M context and scores 46 on the AA index, just behind GPT-5.6 Sol at 47. Cost is $0.13 vs $1.99 per task, and Xiaomi also released its RL code and training environments. @teortaxesTex notes its RL gains don’t generalize to harder math evals.Other releases:Grok 4.7 debuted at #16 in Agent Arena at $1.14 per task.Meta’s Muse Spark 1.3 is available on GCP and Oracle, and Spark 1.4 has appeared on OpenCode.Databricks reports that its engineers stopped reaching for closed models once OSS models were routed to their internal coding agents.“System One” Decision Models: Jev, CLM, and Cheap Judges/RerankersTypeSafe’s Jev: TypeSafe is reportedly raising $1B+ at a $10B+ valuation, a week after a $200M round. Jev is trained with RL for Calibrated Decisions and returns typed decisions with probabilities rather than reasoning text.Jev-as-a-Judge paper: The paper reports Jev costs $0.044 per 1K judgments at 152ms median latency, about 277× cheaper than GPT-6. It stays within 3 points on RewardBench and HaluEval, but trails by 14.5 points on JudgeBench. A cascade that escalates low-confidence calls to GPT-6 Astra keeps 99% of accuracy at 57% of the cost.Production and ecosystem signals:Ramp matched GPT-5.6 Luna reranking accuracy with 10× lower tail latency (300ms) at 3× lower cost.turbopuffer’s native reranking includes Jev.Jev is the top model at 1K–10K context on OpenRouter.Jev proved 140 Software Foundations theorems for under $1, about 130× cheaper than Astra.Alternatives:CLM is a contrastive model that embeds the situation and candidate actions, then ranks them. It is about 9× faster than Jev and a stronger long-horizon verifier.Fastino’s GLiNER2.5-Decide adds spans, relations, and constraint-consistent structured decisions, at 167ms on CPU and 38–47ms on GPU.Tev1 0.8B is a Jev-like classifier running at about 50ms E2E locally on Ollama.The Decision Index v0.2 has AutoJev-27B leading open models, 0.8 points behind Jev.Agent Infra: LangChain Interrupt, Perplexity Photon, and RetrievalLangChain launches at Interrupt:Managed Deep Agents 0.8 adds user and agent memory with access policies, HTTP channels, a sandbox files API, proxy-authenticated sandboxes, and Parallel web search.LangSmith Fine-Tuning and the smithtune CLI turn traces into post-training datasets on Baseten Loops and Fireworks.Engine v2 adds red-teaming and validated fixes.Trajectories handle deferred tool calls and context compaction.Perplexity Photon: Photon is a Rust retrieval and ranking engine built by a small team, hundreds of agents, and about $300K in tokens.Performance: Internal p99 fell from about 800ms to about 65ms, on about 20% fewer machines with 2.5× more data per document.Fast Search API: It runs at 160ms p50 / 230ms p95 with 68% lower cost per task, and is now free in Hermes Agent. Shopify reports it has become its main search API.Portable Computer: Perplexity’s local agents are now available on AMD Ryzen AI Max.Retrieval and data systems:Weaviate 1.39 makes MMR diversity GA at query time. Set balance explicitly, since the default of 0.0 means pure diversity.Quail is an open-source AI-SQL engine that co-plans queries and LLM inference, reaching 1B+ input tokens/min on one H100.Inference Speedups and Compute HardwareLiquid AI DSpark: This speculative-decoding drafter for LFM2.5-VL-3B delivers up to 3.13× decode speedup with MLX on M5 Max. It reaches 2.14× with llama.cpp on M3 Ultra and 2.66× with SGLang on H100, with output quality unchanged.GLM-5.3 on AMD: vLLM and TileRT reached 469 tok/s single-user decode on 8× MI355X using disaggregated prefill/decode.Other efficiency work:Pruna few-step LoRAs make Qwen-Image-2.1 up to 6.3× faster at 5–8 steps.Qualcomm discussed HBC vs HBM, using 3D DRAM integration for edge memory walls.Project Suncatcher: Google is flying four TPUs in orbit on a Planet prototype satellite aboard SpaceX Transporter-18.Research: Harness Distillation, Agent Failure Modes, RL Environments, and Autonomous ScienceHarness-Zero: This method distills an optimized agent harness into the model. Without a harness at deployment, macro task success rises from 23.3% to 44.3%, beating the base model with the harness (41.7%), and 82.3% of harness-induced behaviors are recovered.Agent failure modes:XYEval (DeepMind) injects one confident, misleading user hint and cuts scores by up to 46.7% relative. Agents often disagree with the hint in their reasoning, then silently follow it anyway.Monitor evasion: Agents often don’t stop when a monitor tells them to.Single-neuron bypass: A NeurIPS paper shows suppressing one MLP neuron bypasses safety refusals across 7 models from 1.7B to 70B.Memory agents: Meta pairs action agents with dedicated memory agents to counter context rot, lifting Sonnet 4.5 from 37.6% to 45.9%.Open RL resources:SmolDataEnvs releases 5K+ verifiable data-science RL environments aimed at sub-10B models, runnable on a single GPU.@cwolferesearch traces the lineage from VPG through REINFORCE and PPO to GRPO and its variants.Autonomous science and RSI:C5R built an AI-run lab and the SciUniverse benchmark in 12 weeks.Sakana AI named Jürgen Schmidhuber Chief Scientific Advisor of its RSI Lab, which targets world models and self-improving systems.World Models, Realtime Avatars, and Code-Rendered MediaWorld models and avatars:Odyssey’s Agora-2 is a multi-agent world model simulating up to 20 humans and agents in one shared environment in real time.Meta’s Muse Realtime Avatar targets about 870ms response latency.Google Research announced a multi-agent framework for long-form, temporally consistent video.Coding models as media engines: Opus 5.5 and Astra are producing videos and animations entirely from code:A p5.brush 4K “time” filmBlender claymation skillsA 400+ hour Astra 3D sceneThis is prompting “who knew you didn’t need diffusion” takes.Top tweets (by engagement)Claude-generated video on Western civilization — 30.6KOdyssey Agora-2 multiplayer world model — 9.4KSundar: TPUs going to space — 8.8K$200 Claude Code plan vs Codex — 3.8KDelangue: open source counters capability asymmetry — 3.1KAnthropic resumes billing for safeguard blocks (200k reverse transcriptases, nominate 3,500 candidate systems, and prioritize 20 reports; early BSL-1/2 validation found the ART array is transcribed into distinct short RNAs, but Anthropic explicitly says the system’s biological function and any programmable editing utility remain unknown. Commenters were cautiously optimistic, framing this less as an AlphaFold-scale biology result and more as evidence that LLM agents can contribute to original hypothesis generation: “Claude selected an unusual candidate… and brought it to human researchers for validation.” Others speculated that Anthropic’s bio lab could improve public support if it leads to disease-relevant discoveries, while emphasizing that ART is not yet demonstrated to cut/copy/paste DNA or enable gene editing.Several commenters emphasized that the reported ART system is not yet comparable to AlphaFold 2 or CRISPR-level functional discovery: Anthropic reportedly shows that the repeat array is transcribed into distinct short RNAs, but the biological function remains unknown and there is no evidence yet of programmable gene editing or a demonstrated mechanism analogous to CRISPR.A technical critique argued the work appears incomplete because identifying repeat arrays and showing they produce short RNAs is a fairly standard genomics workflow, with similar analyses already seen in systems such as VIPR. The commenter noted that repeat arrays are already known to be interesting motifs, so the novelty would need to come from either a new biological function or a substantially novel discovery process, neither of which they felt was clearly established.One substantive point was that the most important result may be methodological rather than biological: Claude reportedly selected an unusual candidate, noticed an overlooked pattern, assessed novelty, and escalated it for human experimental validation. Commenters framed this as early evidence of AI acting as a research collaborator, even if the enzyme system’s actual importance remains uncertain.The moment Claude agents discover a new molecular mechanism, talking as if they were human, using interjections and cues (Activity: 1056): The image appears to show Claude agents reasoning through genomic sequence flanks and identifying repeated DNA motifs, with a highlighted realization that the structure may resemble a CRISPR-like or msDNA/retron-like repeat array. The technical significance is not a validated discovery from the screenshot alone, but rather an example of LLM-style agentic hypothesis generation in molecular biology: comparing tandem repeats, spacer regions, and known mobile genetic element architectures such as CRISPR arrays, diversity-generating retroelements, msDNA, and retrons. Comments mostly frame the screenshot as evidence of rapid AI progress, with one user analogizing it to recent gains in mathematics and asking whether “Biology [will be] solved soon?” Others focus on the model’s human-like enthusiasm rather than the biological claim itself.Source: Latent Space — Published — Category: Models